
Planning and prerequisites
What should be confirmed for high performance computing?
Analyze task types, parallelism, data, runtime and licences before selecting CPU or GPU nodes, interconnects, shared storage and scheduling.
ENTERPRISE HIGH-PERFORMANCE COMPUTING
Organize an expandable, schedulable and verifiable high-performance computing environment around CPU/GPU nodes, high-speed networking, shared storage and job scheduling.
01 Why planning matters
Building HPC is not simply adding servers. Nodes and resources are planned around parallel workloads, data scale, compute type and runtime.
Compute, data and interconnect paths affect one another; adding one resource type alone often does not improve overall job efficiency.
Organize distributed CPU, GPU and memory into an allocatable compute pool.
Allocate compute resources by job demand, queue and business priority.
Match compute nodes, shared storage and network paths to actual data throughput.
Keep task, resource, version, failure and result records for continuous improvement.
02 PLATFORM ARCHITECTURE
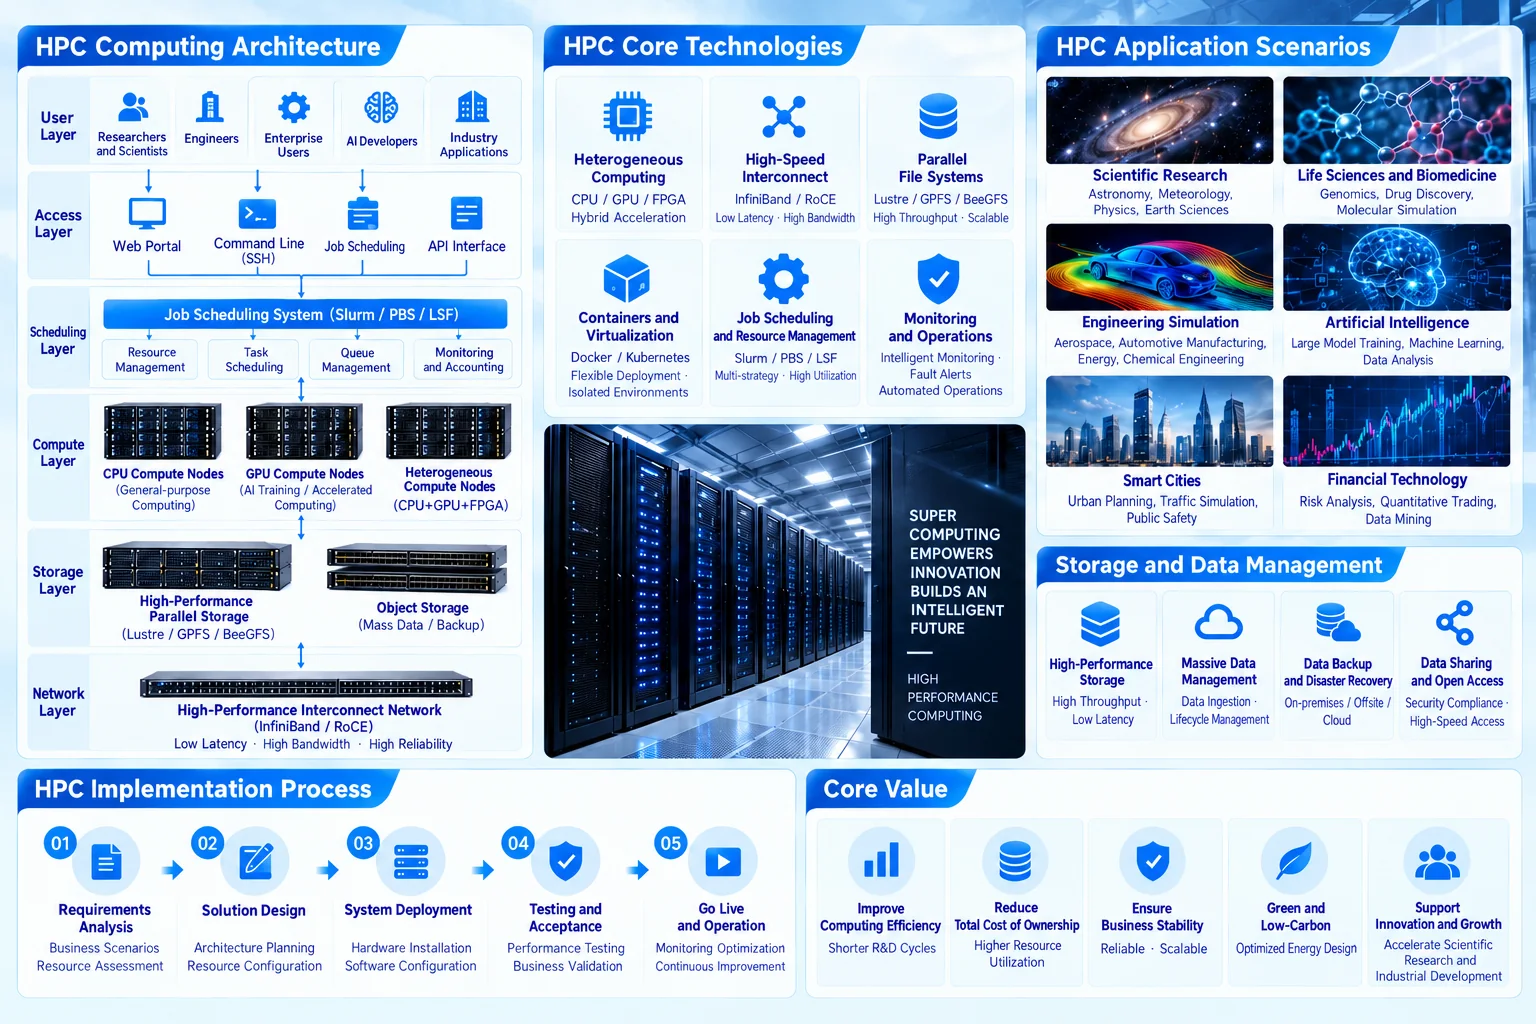
Data movement, node interconnects and shared storage directly affect job efficiency, so the architecture starts with the real data path.
HPC-ENV · system view 01/01
Waiting for node-to-node communication directly affects parallel job efficiency.
Data throughput and access patterns shape storage-path design.
Queue and resource status feed back into continuous policy adjustment.
The architecture follows the real data path and does not assume a fixed equipment scale.
03 JOB SCHEDULING
Implementation validates hardware, systems, the scheduler, software environment and usage workflow together; powering on equipment is not enough.
Confirm task type, dataset, parallel method and performance measures.
Complete node, network, storage, system and scheduler configuration.
Use representative jobs to validate queues, resources, failure and recovery.
Hand over nodes, queues, software environment, monitoring and maintenance records.
04 COMPUTE DENSITY
Node specifications should follow compute density, interconnect method and the expansion plan; GPU nodes, high-speed fabric and cooling conditions together determine high-density capability.
Separate CPU, GPU, memory, parallel and batch tasks.
Select nodes around compute density, interconnect method and the expansion plan.
Bring nodes, quotas, queues and usage permissions into unified scheduling.
05 OPERATIONS
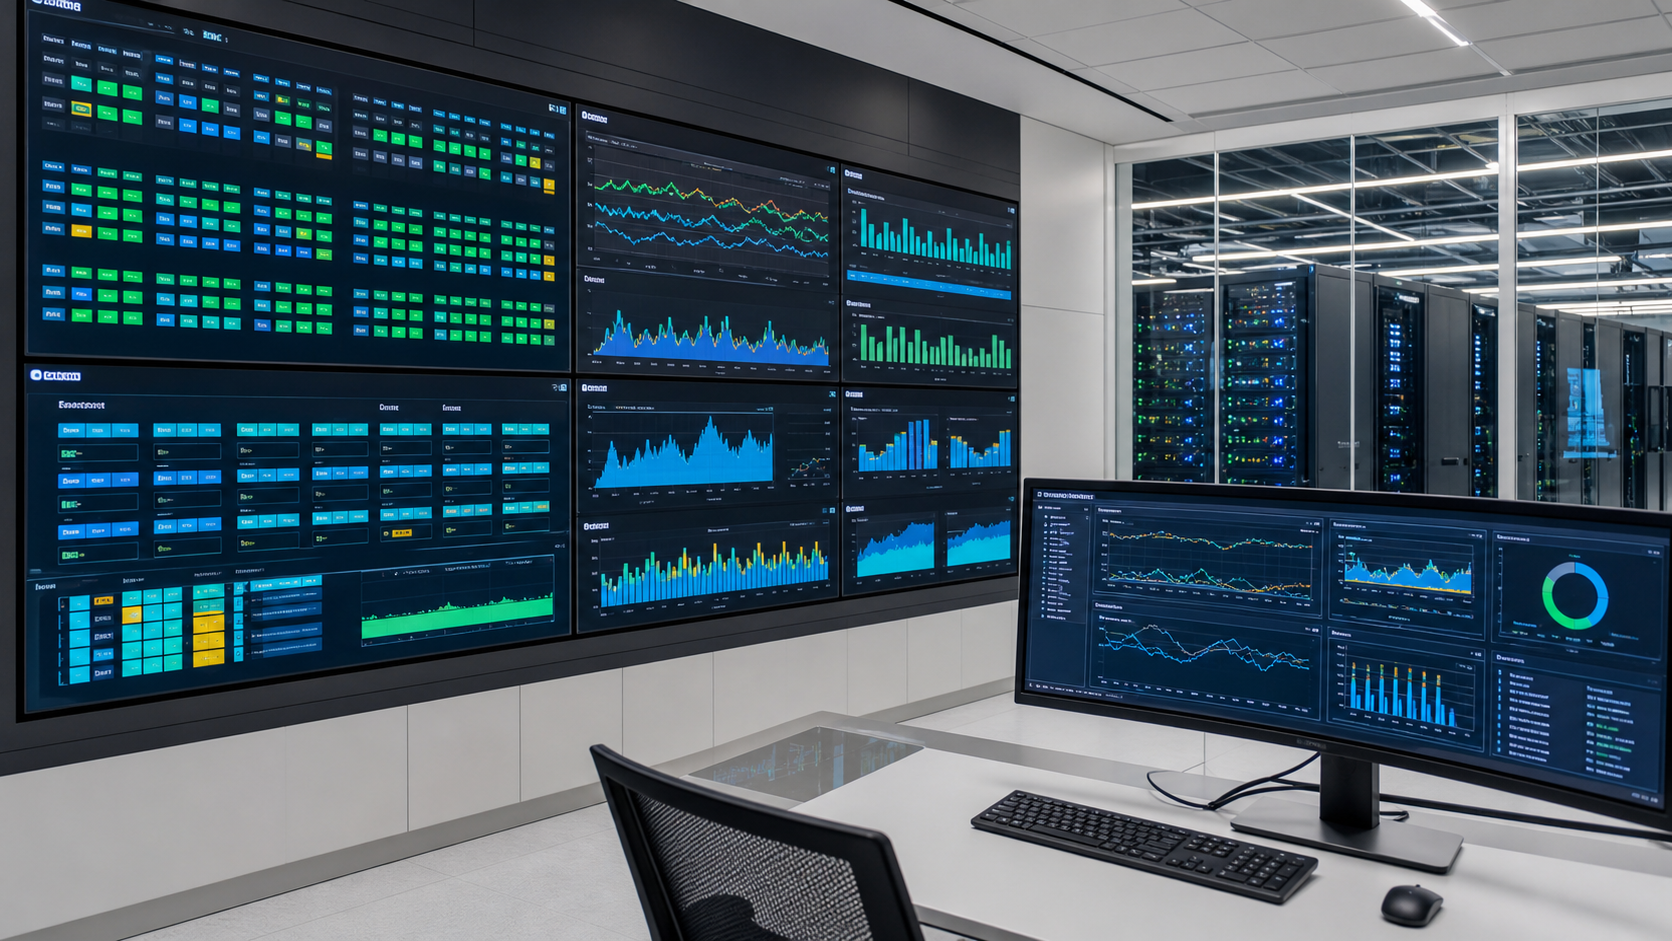
Stable cluster operations require continued attention to resource use, queued tasks, software versions, storage capacity and node state.
Adjust quotas, queues and resource allocation as tasks change.
Manage drivers, runtimes, images and application-version baselines.
Record the causes of node, network, storage and job failures.
06 DELIVERY
Inventory the current environment and build conditions, then confirm the implementation boundary.
Define node, network and storage options around task characteristics.
Complete equipment installation and system, scheduler and network integration testing.
Use representative jobs to validate performance, failure and recovery behavior.
Hand over topology, configuration, monitoring and contact records.
START A CONVERSATION
supports@yuqi-sh.com Contact information is for project communication only
SCOPE & HANDOVER
Plan the HPC platform around actual jobs, scheduling, data paths and acceptance measures before sizing nodes and interconnects. Use server clustering to distinguish node coordination, availability and parallel-work goals. For GPU workloads, confirm application support, memory and representative jobs on the GPU infrastructure page. For HPC implementation, provide representative jobs, software and licences, data volumes, scheduling and target completion times. Validate node, memory, interconnect and storage requirements before pricing supply, deployment, scheduling and acceptance; theoretical throughput does not establish job performance.
What should be confirmed for high performance computing?
Analyze task types, parallelism, data, runtime and licences before selecting CPU or GPU nodes, interconnects, shared storage and scheduling.
What should be checked at handover?
Run representative jobs and verify results, runtime, allocation and data access. Document software environments, scheduling and limitations rather than substituting peak specifications for workload tests.